Predictive maintenance manufacturing: a plant leader's guide
Predictive maintenance (PdM) converts continuous sensor data into scheduled repair orders, giving UK manufacturers a concrete alternative to the costly cycle of reactive breakdowns. Rather than replacing parts on a fixed calendar or waiting for failure, PdM models estimate Remaining Useful Life (RUL) and flag deterioration 7–14 days before an incident, so your maintenance team can act during planned downtime rather than scrambling at 2 AM. The practical outcomes decision-makers care about most are:
Unplanned downtime substantially reduced in well-implemented deployments
Maintenance labour hours notably reduced, freeing technicians for higher-value work
Overall Equipment Effectiveness (OEE) gains from fewer emergency stoppages and shorter Mean Time to Repair (MTTR)
A warning window long enough to order parts at standard cost rather than emergency premium
The single recommended next step: design a timeboxed 90-day pilot on one or two critical assets, set a clear go/no-go gate at day 90, and use that evidence to justify a wider rollout. Innovate UK funding routes and Sentient Concepts’ end-to-end delivery model can both reduce the cost and risk of that first pilot.
Table of Contents
What predictive maintenance is and why manufacturers adopt it
Predictive maintenance is a condition-based strategy that uses sensor data, signal processing, and machine learning models to forecast when a specific asset is likely to fail, then triggers a maintenance intervention before that failure occurs. It sits between two less efficient extremes: reactive maintenance, which responds after failure and carries the highest disruption cost, and preventive maintenance, which replaces or services parts on a fixed schedule regardless of actual condition, often generating unnecessary labour and parts spend.
The business case is straightforward. Unplanned stoppages cost manufacturers a high amount per hour depending on sector and process criticality. A single avoided failure on a critical press or conveyor drive can recover a significant portion of the cost of a PdM pilot. Beyond the headline downtime figure, PdM reduces the parts premium associated with emergency procurement, lowers the frequency of over-maintenance on assets that are performing well, and creates a data record that supports regulatory compliance and asset lifecycle decisions.
Consider a stamping press in an automotive body shop. Under a reactive regime, a bearing failure stops the line without warning. Under a fixed-interval preventive schedule, the bearing may be replaced at 2,000 hours even when it has 800 hours of useful life remaining. A PdM system monitoring vibration and temperature on that bearing detects the characteristic frequency shift of early spalling, raises an alert with a predicted failure window, and the maintenance team schedules a bearing change during the next planned weekend shutdown. The press never stops unplanned, the bearing runs to near-end-of-life, and the technician arrives with the correct part already on the shelf.
Systematic reviews of PdM adoption consistently identify data gaps and difficulties measuring ROI as the primary barriers to wider uptake, not the technology itself. That means the organisations that invest in clean data pipelines and clear KPI definitions from day one gain a structural advantage over those that treat PdM as a pure technology purchase.
How predictive maintenance works in practice
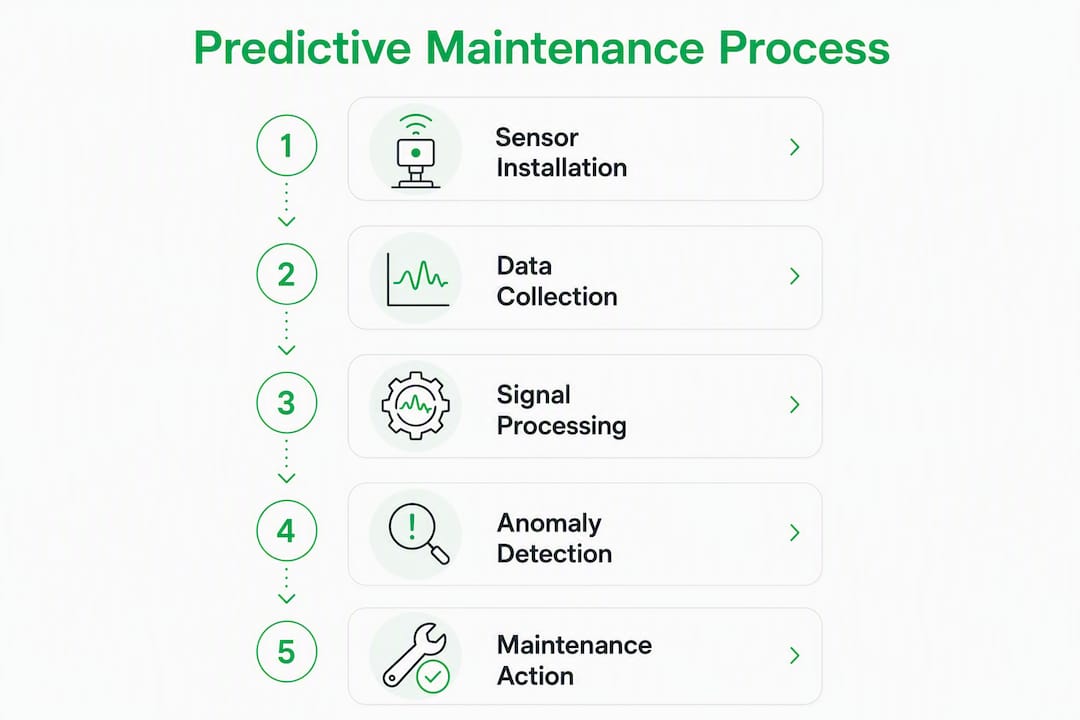
The technical pipeline has six stages, each of which must be designed deliberately rather than assembled ad hoc.
Sensing and data collection. Sensors capture the physical signals that precede failure. Common types include:
Vibration accelerometers (detect bearing wear, imbalance, misalignment)
Temperature sensors and thermal imaging cameras (motor windings, gearboxes, electrical panels)
Acoustic emission sensors (detect micro-cracking, cavitation, seal leaks)
Pressure transducers (hydraulic and pneumatic systems)
Current and power analysers (motor load signatures, efficiency degradation)
Sampling cadence matters as much as sensor choice. High-frequency vibration data captures bearing defect frequencies but generates large data volumes; temperature data sampled at several-second intervals is usually sufficient for thermal monitoring. Getting the signal-to-noise ratio right at the edge, before data leaves the asset, prevents downstream model degradation.
Signal processing. Raw sensor streams are filtered, windowed, and transformed into features. Fast Fourier Transform (FFT) converts time-domain vibration signals into frequency spectra where bearing defect frequencies appear as distinct peaks. Statistical features such as RMS, kurtosis, and crest factor summarise signal health in compact form.
Anomaly detection vs RUL estimation. These are two distinct modelling objectives. Anomaly detection flags when a signal deviates from a learned baseline; it is fast to deploy and works with limited failure history. RUL estimation predicts the remaining operating time before failure; it requires run-to-failure training data but gives schedulers a concrete planning horizon. For most UK plants starting out, anomaly detection is the pragmatic first step, with RUL models introduced once sufficient failure data accumulates.
Decision hand-off. The model output must translate into a maintenance action, not just a score. Well-designed systems generate an automated work order in the CMMS (Computerised Maintenance Management System) or ERP, attach a diagnosis, suggest the required parts, and propose a scheduling window. Without this integration, alerts pile up in a dashboard and technicians ignore them.
Pro Tip: Start with rotating equipment — motors, pumps, fans, gearboxes — because their failure modes are well-characterised, sensor placement is straightforward, and the signal-to-noise ratio is high. This gives your first models the best chance of producing alerts that maintenance teams trust.
Choosing the right technology architecture
Architecture decisions made early in a PdM programme are expensive to reverse. The three dominant patterns each suit different plant contexts.
Edge-first processing runs inference on a gateway or industrial PC close to the asset. It suits plants with unreliable WAN connectivity, strict OT/IT network separation, or latency requirements below one second. The trade-off is higher hardware cost per site and more complex model deployment.
Cloud-first centralises data ingestion, processing, and model serving in a managed cloud environment. It is appropriate for plants with reliable connectivity, multi-site deployments where shared models add value, and organisations that lack on-site ML infrastructure. Latency is acceptable for most PdM use cases where the warning window is measured in days, not milliseconds.
Hybrid architectures run lightweight anomaly detection at the edge and send aggregated features to the cloud for RUL modelling and fleet-level analytics. This is the most common production pattern for UK manufacturers with mixed connectivity across sites.
Connectivity choices matter. OPC-UA is the preferred protocol for structured machine data in modern industrial environments; MQTT suits lightweight telemetry over constrained networks. Both require careful security configuration: default credentials, unencrypted channels, and flat OT networks are the most common cybersecurity vulnerabilities in industrial deployments.
For data platforms, time-series databases (InfluxDB, TimescaleDB, or cloud-native equivalents) handle high-frequency sensor streams more efficiently than relational databases. Asset hierarchy and consistent tagging conventions are foundational: a model trained on “Motor_Line3_Pump2” cannot be reused on “M3P2” without a mapping layer.
Selecting the right ML algorithm should follow a structured framework that weighs dataset characteristics, interpretability requirements, and prediction horizon rather than defaulting to the most complex available model. A gradient-boosted tree on well-engineered features often outperforms a deep neural network on moderate-sized datasets. The integration and architecture decisions that connect OT data sources to ML pipelines are where most PdM projects encounter their first serious delays.
MLOps for production PdM requires: model versioning, automated retraining triggers when data drift is detected, shadow deployments to validate new model versions before they generate live work orders, and a rollback strategy. Without these, a model that was accurate at go-live degrades silently as asset behaviour changes.
A practical implementation roadmap for UK plants
A structured programme reduces the risk of the most common failure mode: a technically successful pilot that never scales because the organisation was not ready.
Readiness assessment (weeks 1–2). Audit existing sensor coverage, CMMS data quality, failure history records, and IT/OT network topology. Identify the two or three assets with the highest downtime cost and the clearest failure modes. Assign a cross-functional team: plant manager, head of maintenance, IT/OT lead, and procurement.
Pilot design (weeks 2–3). Select one or two critical assets. Define KPIs (OEE delta, MTTR reduction, alert precision). Set a 90-day timebox. Agree the go/no-go gate criteria before instrumentation begins.
Instrument assets (weeks 3–5). Install sensors, configure sampling rates, validate signal quality. Capture technician knowledge as labelled events in the CMMS — this tribal knowledge accelerates model training significantly.
Data pipeline build (weeks 4–6). Establish ingestion, storage, and feature engineering pipelines. Validate data completeness and latency end-to-end.
Model development (weeks 6–10). Train anomaly detection models on baseline data. If run-to-failure records exist, develop RUL models in parallel. Validate on held-out data and review with maintenance leads.
CMMS/ERP integration (weeks 8–11). Connect model outputs to work order generation. Define alert thresholds, escalation paths, and parts pre-ordering triggers.
Validation and go/no-go gate (week 12–13). Review alert precision, false positive rate, technician acceptance, and early OEE/MTTR movement against the agreed criteria. Decision: scale, iterate, or hold.
Scale-up planning. Extend to additional assets and sites using the validated architecture and operating procedures.
Pilot checklist:
Critical asset selected with documented failure history
KPIs defined and baseline values recorded
90-day timebox confirmed with stakeholders
Data sources and access rights confirmed
Technician training scheduled
Work order templates updated
Spares strategy reviewed for pilot assets
Pro Tip: Do not wait for a perfect dataset before starting. Begin with existing operational data, however imperfect, and iteratively refine models as more labelled events accumulate. The first 90 days are about proving the pipeline and building organisational trust, not achieving statistical perfection.
Measuring ROI and setting the right KPIs
Finance and operations leaders need a consistent measurement framework before a pilot begins, not after.
Core KPIs:
KPI | Definition | Measurement method | Typical UK target |
OEE | Availability × Performance × Quality | CMMS + production data | Target measurable improvements |
MTTR | Mean Time to Repair | CMMS work order close times | Target meaningful reduction |
MTBF | Mean Time Between Failures | CMMS failure records | Aim to increase average interval |
Cost per failure | Total failure cost ÷ failure count | Finance + CMMS | Aim to reduce costs per incident |
Alert precision | True positive alerts ÷ total alerts | Model monitoring | Aim for high precision in production |
Parts inventory turns | Parts consumed ÷ average inventory value | ERP | Aim to improve inventory efficiency |
A worked ROI example. Assume a food processing line with two critical conveyor drives. Each unplanned stoppage costs approximately £40,000 in lost production and emergency labour (conservative, given the US$50,000–US$250,000 per-hour range cited for manufacturing broadly). The plant experiences four such stoppages per year on these assets: £160,000 annual failure cost. Sensor hardware at roughly US$215 per rotating asset (after a ~73% price decline since 2018) represents a modest capital outlay. Add integration, platform, and managed operations costs, and a well-scoped pilot typically reaches payback within 12–18 months on high-criticality assets.
Cost categories to budget:
Sensor hardware and installation
Edge gateway or cloud platform licences
Data engineering and integration (often the largest single cost)
Model development and validation
CMMS/ERP integration
Technician training and change management
Ongoing managed operations, retraining, and support
The ongoing operations cost is the one most frequently underestimated. A model that is not retrained as asset behaviour changes will degrade, generating false positives that erode technician trust and ultimately kill adoption.
Common pitfalls and how to avoid them
Systematic reviews confirm that the main barrier to PdM success is rarely algorithm performance. It is the absence of an integrated strategy across data engineering, MLOps, and operational maintenance workflows.
Common pitfalls and mitigations:
Poor data quality. Sensor dropouts, inconsistent timestamps, and missing failure labels corrupt model training. Mitigation: audit data completeness before model development begins and establish data quality SLAs with the OT team.
Scarce run-to-failure data. Most assets have never been allowed to fail to destruction. Mitigation: use anomaly detection as the first model type; consider GAN-based data augmentation (discussed in the advanced practices section) for RUL modelling when failure records are thin.
Organisational resistance. Maintenance technicians who distrust model outputs will ignore alerts. Mitigation: involve technicians in pilot design, show them the signal evidence behind each alert, and track false positive rates transparently.
Unclear decision workflow. An alert that reaches a dashboard but has no defined owner or response protocol is wasted. Mitigation: map the alert-to-work-order workflow before go-live and embed it in CMMS templates.
Cybersecurity gaps. Connecting OT assets to data pipelines expands the attack surface. Mitigation: enforce network segmentation, encrypted protocols, and access controls from day one; do not treat security as a post-deployment task.
Vendor lock-in. Black-box platforms with proprietary data formats make it difficult to retrain models or switch providers. Mitigation: require open data formats, model portability, and managed-ops SLAs in any contract.
Pro Tip: Align your predictive models directly with maintenance decision objectives from the outset. Training a model purely to minimise prediction error, then separately optimising the maintenance schedule, is a two-step process that introduces avoidable regret. The integrated estimate–optimise (IEO) approach, discussed in the advanced practices section, addresses this directly.
Where PdM delivers the strongest results by sector
The assets worth instrumenting first differ by sector, and the failure modes that matter most vary accordingly.
Automotive. Body shop stamping presses, welding robots, and conveyor drives are the highest-priority assets. Bearing wear and servo motor degradation are the dominant failure modes. Vibration and current signature analysis give 7–14 day warning windows on these assets, enough time to schedule bearing changes during weekend shutdowns. A single avoided press stoppage on a high-volume line can recover sensor and platform costs over a meaningful period.
Food and beverage. Filling lines, homogenisers, and refrigeration compressors carry the highest downtime cost because stoppages trigger product waste and hygiene compliance events. Temperature and vibration monitoring on compressors, combined with acoustic emission on seals, are the most effective sensor strategies. The regulatory requirement to document equipment condition for food safety audits makes PdM data doubly valuable.
Pharmaceuticals. Tablet presses, coating pans, and HVAC systems in cleanroom environments are the priority assets. The sector’s strict GMP (Good Manufacturing Practice) requirements mean that any maintenance intervention must be documented and validated. PdM systems that integrate directly with the CMMS and produce audit-ready records reduce the compliance overhead of condition-based maintenance significantly.
Heavy industry (steel, cement, aggregates). Kiln drives, mill motors, and conveyor gearboxes operate under extreme load and are expensive to replace. Thermal imaging and vibration monitoring on these assets can detect early-stage gear tooth wear and winding insulation degradation months before failure. The long lead times for replacement parts in this sector make the extended warning window particularly valuable.
Asset prioritisation guidance: start with assets that combine high failure cost, moderate failure frequency, and well-understood failure modes. Assets that fail rarely and unpredictably (low frequency, random failure) are poor candidates for a first pilot because there is insufficient data to train reliable models.
UK-specific considerations for plant leaders
Implementing PdM in a UK plant involves procurement, data governance, funding, and regulatory dimensions that are distinct from generic guidance.
Procurement checklist:
Require open data formats and model portability in all vendor contracts
Include managed-ops SLAs covering uptime, retraining cadence, and alert response times
Specify data residency requirements (UK or EEA data centres) in cloud platform agreements
Define exit provisions and data handover obligations at contract end
Data residency and GDPR. Operational sensor data from manufacturing equipment does not typically constitute personal data under UK GDPR, but employee-linked data (technician work records, shift logs used as model features) does. Establish a lawful basis for processing any employee-linked data, anonymise where possible, and document the data flows. For cloud deployments, confirm that the platform provider holds UK or EEA data residency and that international transfer mechanisms are in place if data leaves the UK.
Funding routes. Innovate UK runs regular funding competitions relevant to smart manufacturing and Industry 4.0 adoption, including the Made Smarter programme in partnership with regional growth bodies. The UK Catapult network (particularly the High Value Manufacturing Catapult) provides technical support and co-investment for manufacturers piloting advanced technologies. These routes can materially reduce the capital cost of a first PdM deployment.
Standards and safety. The British Standards Institution (BSI) publishes guidance relevant to condition monitoring (BS ISO 13374 series) and asset management (BS ISO 55000 series). Safety-critical assets in sectors such as pharmaceuticals, food, and heavy industry should have PdM alert thresholds reviewed against existing safety cases and PSSR (Pressure Systems Safety Regulations) or PUWER (Provision and Use of Work Equipment Regulations) obligations. Integrate PdM outputs into existing asset management policies rather than treating them as a standalone system.
Advanced practices that raise PdM success rates
Three research-backed techniques are changing how practitioners design production-grade PdM programmes.
Integrated estimate–optimise (IEO) frameworks. The conventional approach trains a model to predict RUL as accurately as possible, then separately optimises the maintenance schedule. Research shows this two-step process introduces avoidable decision regret. An integrated estimate–optimise framework embeds the maintenance cost objective directly into model training, reducing average maintenance regret by up to 22% compared with traditional methods. The implementation implication: define your maintenance cost structure (intervention cost, failure cost, opportunity cost of unnecessary downtime) before model development begins, and use it to shape the loss function.
GAN-based data augmentation. Most plants have abundant normal-operation data but very few run-to-failure sequences. Generative Adversarial Networks (GANs), specifically WGAN-GP variants, can generate synthetic run-to-failure sequences that stabilise RUL distributions and improve model robustness when real failure data is scarce. This technique is particularly relevant for high-value assets that are never deliberately run to failure. The implementation implication: if your pilot asset has fewer than 10–15 documented failure events, evaluate GAN augmentation before concluding that RUL modelling is infeasible.
Risk-aware clustering for opportunistic maintenance. Rather than scheduling each asset’s maintenance independently when its RUL threshold is crossed, risk-aware clustering groups components with similar RUL profiles and optimises a single maintenance visit to service multiple assets simultaneously. This reduces total expected maintenance cost and minimises the number of production interruptions. The implementation implication: design your scheduling logic to consider asset clusters, not individual assets in isolation.
Pro Tip: Combine RUL prediction with opportunistic scheduling logic. When one asset on a line triggers a maintenance window, check the RUL of adjacent assets and service those approaching their threshold at the same time. This single change can reduce total maintenance interventions by 15–25% on a well-instrumented line.
Your first 90 days: a concrete action plan
Moving from this guide to a live pilot requires a structured sequence of decisions and actions.
Week 1: Convene the core team. Plant manager, head of maintenance, IT/OT lead, and procurement. Agree the pilot scope, budget envelope, and decision authority.
Week 2: Asset selection and baseline. Identify the one or two assets with the highest unplanned downtime cost. Pull three years of CMMS failure history. Record baseline OEE, MTTR, and MTBF.
Week 3: Data audit. Assess existing sensor coverage, historian data quality, and network topology. Identify gaps that must be closed before modelling begins.
Week 4: Vendor/partner engagement. Issue a brief scope to potential delivery partners. Evaluate against: data engineering capability, ML model development, CMMS integration experience, and managed-ops commitment post-deployment.
Weeks 5–6: Sensor installation and pipeline build. Install any additional sensors. Establish the data ingestion pipeline and validate end-to-end data flow.
Weeks 7–10: Model development. Train initial anomaly detection models. Review outputs with maintenance leads. Adjust thresholds based on operational feedback.
Weeks 11–12: Integration and soft launch. Connect model outputs to CMMS work order generation. Run in advisory mode (alerts visible but not yet mandatory) to build technician confidence.
Week 13: Go/no-go gate. Evaluate against agreed success criteria:
Data completeness >90% over the pilot period
Alert precision >65% (true positives as a share of total alerts)
At least one confirmed early detection event with documented cost avoidance
Technician acceptance confirmed by the head of maintenance
Decision gate outcomes:
Go/scale: criteria met; proceed to additional assets and sites with the validated architecture.
Iterate: partial criteria met; extend the pilot by 30 days with specific improvements defined.
Hold: fundamental data or organisational barriers identified; address root causes before reinvesting.
Key takeaways
Predictive maintenance in manufacturing delivers measurable downtime reduction and OEE gains when it is built on clean data pipelines, decision-aligned models, and a managed operations commitment that extends well beyond initial deployment.
Point | Details |
Warning window is the core value | PdM systems typically provide 7–14 days’ advance warning, enabling planned repairs instead of emergency responses. |
Downtime reduction is substantial | Well-implemented deployments reduce unplanned downtime by up to 50–70% and maintenance labour hours by 20–30%. |
Architecture decisions are hard to reverse | Choose edge, cloud, or hybrid based on connectivity and latency needs before instrumentation begins. |
Managed operations protect ROI | Models degrade without retraining; budget for ongoing operations from day one, not as an afterthought. |
Sentient Concepts as delivery partner | Sentient Concepts provides end-to-end delivery from data engineering and model development through to managed AI operations for UK manufacturers. |
Why end-to-end accountability changes PdM outcomes
The most common reason PdM programmes underperform is not a weak algorithm. It is the handoff. A consultancy designs the strategy, a systems integrator installs the sensors, a data science team builds the models, and then the plant is left to operate a system none of those parties feel responsible for maintaining. Six months later, the models are stale, the alerts are noisy, and the maintenance team has stopped trusting the system.
The evidence supports this view. Systematic reviews identify the absence of integrated strategy across data engineering, MLOps, and operational workflows as the primary barrier to PdM success, not algorithm quality. The IEO research reinforces it: optimising a model in isolation from the maintenance decision it is meant to support produces structurally worse outcomes. These are not implementation details. They are architectural flaws that no amount of model tuning can fix after the fact.
What actually protects ROI is a single accountable partner who holds the data pipeline, the models, and the operational run in one contract. That means SLAs on alert quality, defined retraining cadence, and a named team that answers when the system produces a false positive at 3 AM on a Sunday. It also means the AI operating model is designed for production from day one, not retrofitted after a successful demo.
Pro Tip: When evaluating any PdM delivery partner, require a written managed-operations commitment in the contract: minimum alert precision SLA, retraining frequency, model version control, and a defined escalation path. A partner unwilling to commit to these terms is implicitly telling you they plan to hand the system over and walk away.
How Sentient Concepts delivers PdM for UK manufacturers
Manufacturers who want to move from this guide to a live pilot without assembling a fragmented supply chain of consultants, integrators, and data scientists have a direct route. Sentient Concepts delivers predictive maintenance programmes end-to-end: from the initial readiness and data diligence assessment that scopes your pilot, through data and platform engineering that builds the ingestion and feature pipelines, to model development, CMMS integration, and managed AI operations that keep the system performing after go-live.
The commercial model is straightforward: a timeboxed pilot readiness assessment establishes data quality, asset criticality, and architecture fit before any significant capital is committed. That assessment produces a go/no-go recommendation with a costed rollout plan. For manufacturers who proceed, Sentient Concepts holds accountability across the full lifecycle, including model retraining, alert quality SLAs, and ongoing optimisation as asset behaviour evolves. There are no handoffs between strategy, build, and run phases. If you are ready to scope a 90-day pilot, contact the team to request a pilot readiness assessment.
Useful sources
Predictive Maintenance using Machine Learning (arXiv) — A peer-reviewed technical overview of ML approaches to PdM, useful for understanding algorithm families and their application to manufacturing asset data.
Predictive Maintenance Algorithm Based on Machine Learning for Industrial Asset (IEEE Xplore) — IEEE conference paper covering algorithm selection and industrial deployment considerations; relevant for engineering leads evaluating model architectures.
Systematic review of predictive maintenance practices in the manufacturing sector (ScienceDirect) — The most comprehensive literature review available on PdM adoption barriers, ROI measurement challenges, and deployment patterns across manufacturing.
Toward decision-oriented prognostics: An integrated estimate–optimise framework (IEO) — Primary research paper on the IEO framework; essential reading for teams designing models that need to reduce maintenance regret rather than just prediction error.
A conceptual framework for ML algorithm selection for predictive maintenance (ScienceDirect) — Practical framework for matching dataset characteristics and business requirements to appropriate ML algorithm families; useful for avoiding over-engineered model choices.
FAQ
What is the typical failure warning window for predictive maintenance?
PdM systems commonly provide 7–14 days’ advance warning before a failure event, giving maintenance teams enough time to schedule repairs during planned downtime and pre-order parts at standard cost.
How much can predictive maintenance reduce unplanned downtime?
Well-implemented deployments reduce unplanned downtime by up to 50–70% and cut maintenance labour hours by around 20–30%, though results depend on asset criticality, data quality, and operational integration.
What assets should a UK manufacturer instrument first?
Start with rotating equipment — motors, pumps, fans, and gearboxes — because their failure modes are well-characterised, sensor placement is straightforward, and the signal-to-noise ratio supports reliable early models.
How long does a predictive maintenance pilot take?
A 90-day timeboxed pilot covering one or two critical assets is the standard starting point; the go/no-go gate at day 90 determines whether to scale, iterate, or hold based on data completeness, alert precision, and technician acceptance.
How does Sentient Concepts support predictive maintenance in manufacturing?
Sentient Concepts delivers end-to-end PdM programmes for UK manufacturers, covering readiness assessment, data and platform engineering, model development, CMMS integration, and managed AI operations with defined SLAs post-deployment.
Recommended