Quality prediction manufacturing: the reliable hybrid approach
Quality prediction in manufacturing is now reliably achieved by combining structured process-data models with image-based defect detectors and anomaly detection, all delivered on a production-grade data platform. This hybrid, sometimes called predictive quality assessment, moves quality control in manufacturing from reactive end-of-line inspection to a continuous forecast built into the production line itself.
The evidence for this approach is strong. A recent case study using ensemble classifiers on production data reached an overall accuracy of 98.78% and a Cohen’s Kappa of 0.91 for predicting compliance outcomes, provided the underlying feature engineering was done properly. That last condition matters more than the algorithm.
The recommended architecture has three layers:
Supervised tabular models (gradient-boosted trees, ensemble classifiers) for known, labelled defect categories and pass/fail outcomes.
Anomaly detection for the unknown unknowns, the failure modes nobody has labeled yet.
Vision and multimodal models where surface or dimensional defects genuinely need image evidence.
Pro Tip: Don’t start with the model. Start with what a false negative costs you on the line, then size your accuracy target against that number.
Done properly, this combination shortens containment time, cuts scrap, and gets root cause analysis moving hours earlier than manual inspection allows. Sentient Concepts builds these systems for manufacturing clients precisely because the hard part isn’t the algorithm choice, it’s the data engineering and operational discipline that sits underneath it.
Key Takeaways
Reliable quality prediction in manufacturing combines supervised process-data models, anomaly detection, and vision where needed, but only works when built on a properly engineered data foundation.
Point | Details |
Data engineering comes first | Unit genealogy and timestamp normalisation must precede any model, or predictions will be unreliable. |
Match metrics to the task | Use AUROC and F1 for pass/fail, mAP for defect localisation, and Cohen’s Kappa for inspector agreement. |
Hybrid beats single-method | Combine supervised classifiers for known defects with anomaly detection for novel failure modes. |
Validate across lines, not one dataset | Time-based and cross-line testing prevents overly optimistic accuracy claims. |
Continuity drives scale | Sentient Concepts delivers strategy, data engineering, and managed operations under one accountable team, reducing the handoffs that typically stall pilots. |
Table of Contents
What does quality prediction in manufacturing actually cover?
How do you choose between statistical, ML and deep learning models?
How does image-based defect detection fit into quality prediction?
How do you keep quality prediction models reliable in production?
How does a quality prediction pilot scale into full production?
What does a 90-day quality prediction starter plan look like?
Start your quality prediction pilot with an accountable delivery partner
What does quality prediction in manufacturing actually cover?
Quality prediction manufacturing systems typically forecast one of four outcomes: binary pass/fail compliance, a continuous dimensional measurement (wall thickness, torque, fill weight), a surface defect classification, or aggregate yield across a batch or shift. Each outcome demands a different modelling strategy, and conflating them is one of the most common mistakes in early pilots.
Pass/fail prediction is the most tractable starting point because the label already exists somewhere in your test logs. Dimensional prediction is a regression problem and usually benefits from process parameters (temperature, pressure, cycle time) as direct inputs rather than proxies. Surface defect classification leans on image data and needs the vision techniques covered later in this article. Yield prediction aggregates all of the above across a production run and is the hardest to get right early on, because errors compound across every upstream stage.
Prediction adds the most value in three situations:
Escape prevention: catching a defect before it reaches a customer, where the cost of a field failure dwarfs the cost of an extra inspection.
Inspection reduction: replacing 100% manual inspection with a targeted sampling regime once a model can reliably flag high-risk units.
Root cause acceleration: using model feature importance to point engineers at the process parameter that’s actually drifting, rather than waiting for a quality review meeting three days later.
If you’re choosing a pilot, resist the urge to model everything at once. The best quick wins are a single-line pass/fail classifier on your highest-volume product, or a supervised model targeting your single most expensive defect class. Both give you a fast, measurable proof point without asking a fresh data platform to do too much at once. This mirrors the finding that predictive modelling in multi-stage manufacturing needs careful scoping. Trying to predict every quality outcome across every line before you’ve proven one works is how pilots stall.
How do you choose between statistical, ML and deep learning models?
Model selection should escalate in complexity only as far as the problem demands, not as far as the latest paper suggests.
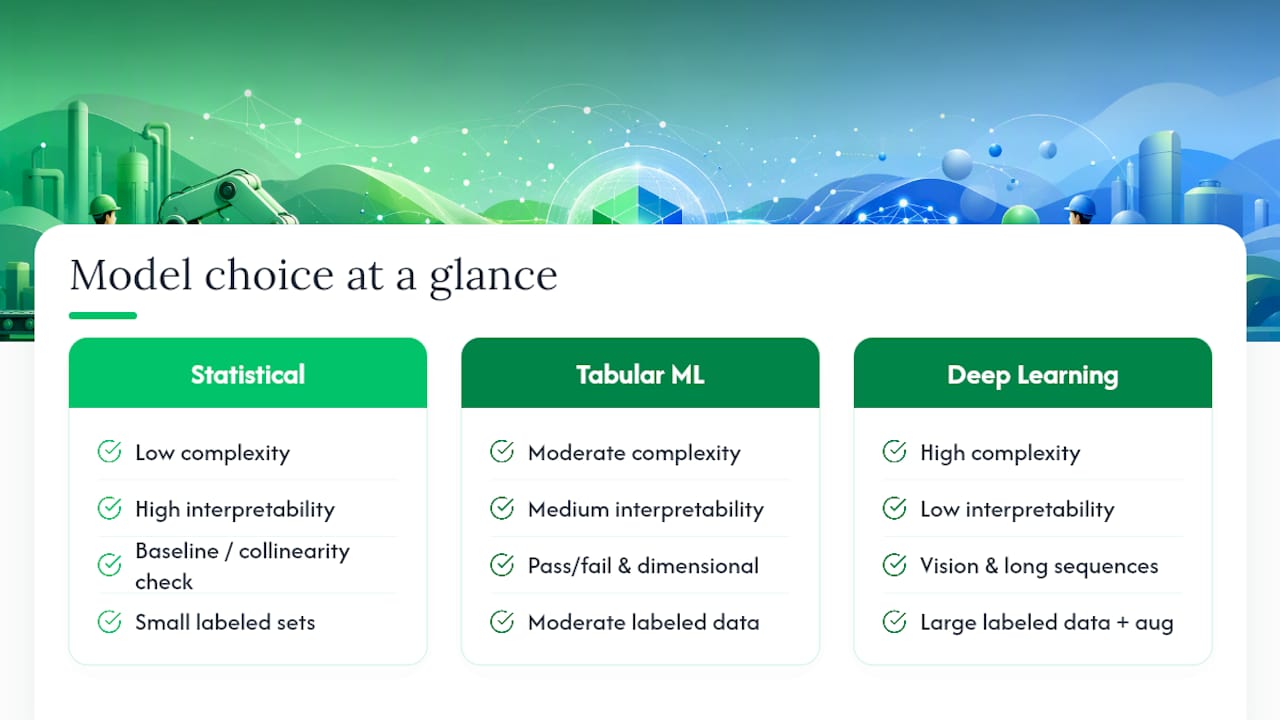
Start with interpretable statistical baselines. Partial least squares (PLS) and principal component regression (PCR) remain genuinely useful, not as a formality, but as a control. Any ML model you build afterwards has to beat that floor by enough to justify its added complexity and reduced interpretability. Statistical baselines also expose collinearity and sensor redundancy that gets hidden inside a black-box model.
Move to tabular ML when relationships are non-linear. Gradient-boosted trees (XGBoost, LightGBM) and random forest ensembles are the workhorse for pass/fail and dimensional prediction on structured process data. They handle mixed data types, missing values, and non-linear interactions without heavy preprocessing. The case study reporting 98.78% accuracy used exactly this class of model, and the paper’s own emphasis was on feature construction, not exotic architecture. Hyperparameter tuning matters, but less than most teams assume: a reasonably tuned gradient-boosted model with good features usually outperforms an aggressively tuned model with poor ones. Compute footprint is modest, these models train on a laptop-class machine and run inference in milliseconds, which matters when you’re deciding between edge and cloud deployment later.
Reserve deep learning for genuinely complex signals. Vision-based defect detection and long, high-dimensional temporal sequences are where deep learning earns its cost. Convolutional networks and transformer-based vision models materially outperform classical computer vision on surface defects with subtle texture or reflectance variation. The trade-off is real: you need more labelled examples, more compute, and more MLOps maturity to keep these models stable in production. If your defect rate is low, and it usually is, in bounds of 1 to 3%, you likely don’t have enough positive examples yet to justify a deep model without synthetic data augmentation.
Hybrid patterns consistently outperform single-method systems. The most effective pattern combines supervised classifiers for known, labelled defect types with unsupervised anomaly detection running in parallel to catch anything that doesn’t match a known category. Industrial expert commentary on hybrid anomaly detection backs this pattern specifically because manufacturing failure modes evolve. A supervised model trained on last year’s defect taxonomy will miss a genuinely new failure mode; an anomaly detector running alongside it will flag the deviation even without a label. Industrial anomaly detection approaches applied to security contexts show the same principle: known-pattern detection and novelty detection solve different problems and neither substitutes for the other.
Pro Tip: Run your anomaly detector for a full production cycle before trusting its alerts. Seasonal and shift-pattern effects (a Monday morning cold-start, a tool change at hour 400) will trigger false alarms until the model has seen a representative range of normal operation.
A practical decision rule: if your defect class is well labelled and stable, use supervised tabular ML. If it’s visual and subtle, escalate to deep learning vision. If you’re worried about what you haven’t seen yet, run anomaly detection alongside whichever supervised model you deploy. Very few production systems should rely on exactly one method.
How does image-based defect detection fit into quality prediction?
Vision systems solve a different problem than tabular models: they catch what process sensors physically cannot see. Getting there starts with unglamorous engineering, not model selection.
Camera positioning, lighting consistency, and AOI station calibration determine model performance far more than architecture choice. A defect detector trained on images with variable lighting will learn to detect lighting changes, not defects. Standardising illumination angle, using polarised or diffuse lighting for reflective surfaces, and locking camera focal distance are the unglamorous prerequisites that make any downstream model trustworthy.
Choosing a detector architecture depends on your speed and label constraints.
Two-stage detectors (Faster R-CNN family) tend to offer higher accuracy on small, subtle defects but run slower, which matters less if inspection happens off the main line.
Single-stage, real-time detectors like YOLO variants trade some accuracy for the throughput needed on high-speed lines. Application-specific adaptations for small, reflective defects have shown mAP@0.5 improvements to 85.3% and 92.2% across two published datasets, though the authors themselves caution that further validation is needed before production deployment, a caveat worth taking seriously rather than treating as boilerplate.
Multimodal methods solve the scarce-label problem that plagues most defect datasets. CLIP-based multimodal frameworks paired with synthetic anomaly generation have reported an AUROC of 99.9% and AUPRO of 98.6% on surface-defect benchmarks, achieved with weakly supervised training rather than the thousands of hand-labelled defect images a traditional detector needs. Synthetic anomaly generation, often built on Perlin-noise-style texture perturbation, manufactures plausible defect examples so the model has something to learn from before real defects have accumulated in your dataset. This also improves explainability, because the model can point to the region it flagged as anomalous rather than issuing a bare classification. Our guide to visual inspection AI covers the practical engineering choices in more depth.
The final step is fusion: vision outputs (a defect score, a bounding box confidence, a texture anomaly measure) become additional features feeding the same tabular model handling your process data, rather than a separate, disconnected judgment. A unit with a marginal vision score and a process parameter drift is a stronger fail signal than either alone.
Which metrics actually validate a quality prediction model?
The metric you choose has to match the task, and using the wrong one is how teams end up celebrating a model that’s actually useless in production.
For pass/fail classification, accuracy alone is misleading when defects are rare. AUROC measures how well the model ranks units by risk regardless of threshold, while precision, recall, and F1 tell you the real trade-off between false alarms and missed defects at your chosen threshold. For any localisation task (finding where on a surface a defect sits), use mAP or AP, the standard in the object detection literature and the metric reported for YOLO-based AOI systems. When your labels come from human inspectors and you want to know if the model agrees with them beyond chance, Cohen’s Kappa is the right choice. The 0.91 Kappa reported in one production case study reflects near-perfect agreement, a genuinely strong result, though achieved on a specific dataset with specific feature engineering that won’t transfer automatically to your line.
Class imbalance is the norm, not the exception, in defect data. Most production lines run at defect rates well under 5%, which means a naive model can hit 95% accuracy by predicting “pass” every time and be worthless. Effective countermeasures include:
Focal loss, which down-weights easy, well-classified examples during training so the model keeps learning from the rare, hard positives.
Stratified sampling and oversampling of minority classes, applied carefully to avoid simply duplicating noise.
Synthetic anomaly generation, the same technique used in multimodal vision detection, applied to tabular process data to manufacture plausible failure examples.
Research on quality prediction methods specifically highlights feature engineering and imbalance handling as the difference between a mediocre and a strong classifier, more than architecture choice.
Validation design is where overly optimistic claims usually creep in. A model validated on a single random train/test split from one balanced dataset will look excellent and fail in production. The right protocol uses time-based splits (train on earlier weeks, test on later ones, because production drifts), cross-line tests (train on Line 1, validate on Line 2, because models that perform well on one line often fail on others), and a shadow-mode period where the model runs alongside human inspection without making decisions, so you can measure real-world precision and recall before it controls anything.
How do you keep quality prediction models reliable in production?
A model that scored 98% accuracy in validation and then sat unmonitored for six months is a liability, not an asset. Deployment decisions and ongoing operations determine whether that accuracy survives contact with a real production floor.
Choose edge or cloud based on latency and connectivity, not preference. A model gating a conveyor decision in under 200 milliseconds needs to run at the edge, close to the sensor. A model producing a shift-level yield forecast can run comfortably in the cloud. Most production architectures end up hybrid: edge inference for real-time gating, cloud aggregation for trend analysis and retraining.
Monitor for three distinct types of drift. Data drift is when input distributions shift (a new supplier’s raw material behaves differently under the same sensor readings). Label shift is when the proportion of defect types changes. Concept drift is when the actual relationship between inputs and outcomes changes, a machine ages, a process parameter that used to predict failure no longer does. Each needs a different detection method and a different response.
Build retraining pipelines before you need them. Waiting until a model visibly degrades to build a retraining pipeline means weeks of bad predictions in the meantime. Our guide to data drift detection covers the monitoring architecture in more depth.
Write the runbook before go-live, not after the first incident. Define who gets paged when the model’s confidence drops below threshold, what the rollback procedure is if a retrained model performs worse than the version it replaced, and what KPIs the quality team has agreed constitute acceptable performance.
Pro Tip: Set a hard rollback trigger, not a judgment call, tied to a specific metric threshold agreed with the quality team before deployment. “We’ll know it if we see it” is how a degraded model stays live for three extra weeks.
Lack of structured post-deployment monitoring is consistently cited as a leading cause of model failure once systems leave the pilot stage, not model accuracy at launch. Our operating model framework for enterprise AI sets out the governance structure that keeps monitoring and retraining from falling through organisational cracks.
How does a quality prediction pilot scale into full production?
Scaling a quality prediction pilot into a sustained capability depends less on model sophistication and more on whether the delivery model maintains continuity from strategy through to operations.
Before committing budget, run three readiness checks: confirm unit genealogy actually links raw material through to finished product across every stage, confirm your labels (pass/fail records, defect classifications) are consistent across shifts and inspectors, and confirm the quality team, plant engineers, and data science function agree on what success looks like before day one.
Sentient Concepts structures delivery in three phases: strategy and use-case prioritisation to identify which defect class or line offers the fastest payback, data engineering and pilot build to prove the model on real production data, and scale and managed operations to extend a proven pilot across additional lines while keeping monitoring and retraining under continuous ownership.
The single biggest failure mode in industrial AI isn’t a weak model, it’s a handoff. The team that builds the pilot moves on, the team that inherits it doesn’t understand the feature engineering decisions, and within two quarters nobody owns the drift alerts. Continuity of ownership from strategy through to managed operations is what separates a pilot that scales from one that quietly dies in a drawer.
A short governance checklist for any procurement conversation, whether with Sentient Concepts or another vendor, should cover: who owns model retraining after go-live, what the data lineage documentation looks like, how model performance is reported against agreed KPIs, and whether the same team that built the pilot stays accountable for its operation. Our manufacturing practice page sets out how this continuity works in delivery terms.
What does a 90-day quality prediction starter plan look like?
You don’t need a data lake and a platform team to start. You need one line, one defect class, and ninety days.
Days 1 to 30 (Discover): Audit data sources on your chosen line, build the unit genealogy key, and confirm label quality with the quality team. Deliverable: a clean, joined dataset covering at least three months of production history.
Days 31 to 60 (Pilot): Train a supervised classifier or an AOI camera pilot on your highest-value defect class, running in shadow mode alongside existing inspection. Deliverable: precision, recall, and false-positive rate measured against human inspectors on live data.
Days 61 to 90 (Measure and plan scale): Quantify the reduction in escaped defects and detection latency, and use those numbers to build the business case for a second line.
Recommended team composition for this window: one data engineer, one applied data scientist, and one quality engineer who understands the failure modes from the shop floor, not just the dataset. That third role is the one teams most often skip, and the one that most often prevents the pilot from solving the wrong problem.
Pro Tip: Track false-positive rate as closely as detection rate from day one. A model that flags too many good units erodes operator trust faster than one that occasionally misses a defect, and lost trust is far harder to rebuild than a model retrain.
Common pitfalls: choosing a defect class too rare to gather enough examples in ninety days (pick your second most common defect, not your rarest), skipping the shadow-mode comparison against human inspectors, and treating the pilot’s success metric as accuracy alone rather than the operational KPI that actually matters, like reduced containment time.
What the research actually tells us to prioritise
The academic literature on quality prediction manufacturing is stronger than most practitioners give it credit for, and weaker in exactly the place most conference talks gloss over: the gap between a benchmark result and a production deployment.
The conventional advice, pick the best architecture, chase the highest benchmark score, gets this backwards. Every source in this piece that reports a strong result also credits feature engineering, data cleanliness, or synthetic label augmentation as the actual driver, not the model family. That’s the uncomfortable truth for anyone hoping a better neural network will fix a fragmented data estate.
If you take one thing from this article, prioritise your unit genealogy and timestamp normalisation before you open a modelling notebook. Everything downstream, including which metric you trust and how quickly you can retrain when drift hits, depends on that groundwork holding up.
Start your quality prediction pilot with an accountable delivery partner
Most manufacturing teams trying to build quality prediction in house hit the same wall: a data scientist builds a strong model in a notebook, then nobody owns turning it into a monitored, production-grade system once the initial project budget runs out. Sentient Concepts is structured specifically to remove that gap, the same team that scopes your pilot also builds the data platform underneath it and stays accountable for running it once it’s live.
Our data and platform engineering services build the unit genealogy, sensor ingestion, and schema work this article treats as a precondition, and our managed AI operations team keeps drift monitoring and retraining running long after go-live. If you’re evaluating where to start, our manufacturing practice page outlines how we scope a first pilot. Get in touch to talk through which line and defect class would make the strongest starting point for your plant.
Sources
Technical teams building on this article’s approach should read the primary sources directly, several report full experimental results and dataset descriptions worth studying in detail.
FAQ
What is QC in manufacturing?
Quality control (QC) in manufacturing is the set of inspection and testing activities used to verify that a product meets specification before it ships. Quality prediction extends QC by forecasting likely defects earlier in the process, reducing reliance on end-of-line inspection alone.
Which ML model is best for prediction?
There is no single best model. Gradient-boosted tree ensembles are typically the strongest choice for structured process data, deep learning vision models suit surface defect detection, and a hybrid combining supervised classifiers with anomaly detection tends to outperform any single method, as reported by practitioners.
What are some important quality metrics for manufacturing?
Key metrics include AUROC and F1 score for pass/fail classification, mAP for defect localisation in vision systems, and Cohen’s Kappa for measuring agreement with human inspectors, particularly in imbalanced datasets where accuracy alone is misleading.
What is quality in manufacturing?
Quality in manufacturing refers to how consistently a product meets its defined specifications, dimensional tolerances, surface finish, functional performance, across every unit produced, not just on average. Predictive quality assessment aims to forecast that consistency before a unit reaches final inspection.
How do you predict product quality before production ends?
You predict product quality by feeding process parameters, sensor readings, and where relevant image data into a trained model that flags high-risk units in real time, rather than waiting for end-of-line testing. Sentient Concepts builds this capability by pairing data platform engineering with production model deployment so the prediction runs continuously on the line, not as a one-off analysis.
Recommended