Vector Database Use Cases: 4 Roles for Search, RAG and Fraud
Vector databases store data as numerical embeddings and search it by meaning rather than by keyword, which is why they now sit behind semantic search, recommendation engines, retrieval-augmented generation and fraud detection. The payoff is faster, more relevant retrieval across text, image and behavioural data. For technology leaders building AI systems, that difference determines whether an LLM hallucinates or answers correctly, and whether Sentient Concepts client teams see automation that actually reduces manual review.
TL;DR:
Sub-100ms latency, high write throughput, and specialized index tuning are essential criteria for choosing a dedicated vector database over extensions.
Hybrid search combining semantic relevance with structured filters is needed for most production systems, favoring platforms with native hybrid support.
Properly selecting an embedding model, monitoring for drift, and regularly updating vectors are critical to maintain relevance and accuracy at scale.
Behavioral vectors for fraud and anomaly detection require extensive historical data and careful threshold calibration to minimize false positives.
Ongoing relevance evaluation and pilot-focused deployment are key to avoiding system degradation and ensuring successful real-world performance.
Table of Contents
How vector databases work
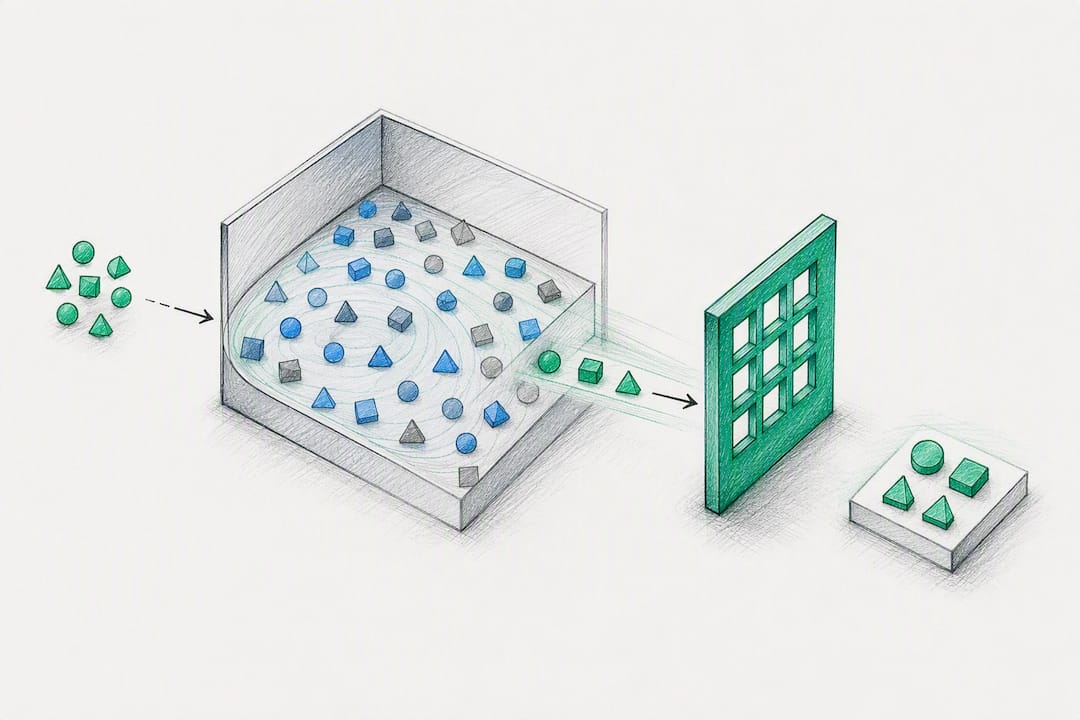
A vector database converts raw content, whether a paragraph, a photo, or a transaction record, into an embedding: a list of numbers with dimensions produced by a machine learning model. Two items that mean similar things end up as numerically close vectors, even if they share no words or pixels in common. That property is the entire mechanism behind semantic search.
Searching billions of these vectors one by one would be too slow for production, so vector databases use approximate nearest neighbour (ANN) indexes instead of exact comparison. The three dominant families, according to a comprehensive survey of vector database management systems, are:
Graph-based indexes such as HNSW, which build navigable layers of connections and trade a small accuracy loss for speed at scale.
Table-based indexes such as IVF, which cluster vectors into buckets and search only the most promising ones.
Quantisation methods such as product quantisation (PQ), which compress vectors to cut memory footprint, often at some cost to precision.
Once the index returns candidates, a similarity metric ranks them. Common metrics include cosine similarity, which suits text embeddings, and Euclidean distance, which works better for spatial or image data. Choosing the right metric is important for search quality.
Pure vector search rarely stands alone in production. Most real queries need metadata filters too, such as “similar products, but only in stock” or “similar clinical notes, but only for this patient.” This is hybrid search: combining semantic ranking with structured attribute filters, and platforms like OpenSearch now build this in natively, alongside sparse-vector support and memory-efficient compression for large indexes.
Pro Tip: Test your similarity metric against a handful of known “should match” and “should not match” pairs before deploying an index at scale. It takes twenty minutes and catches embedding mismatches that would otherwise surface as vague user complaints months later.
Vector database use cases in production today
Before generative AI dominated the conversation, vector databases were already earning their keep in four well-established roles. These remain the backbone of most vector database use cases in live systems, and they are worth understanding on their own terms before layering LLMs on top.
Semantic search. Keyword search fails the moment a user types “affordable laptop for students” and the product catalogue says “budget notebook.” Vector search matches on meaning, not string overlap, which is why enterprises adopt it as unstructured data volumes grow. Support ticket search, legal document lookup and internal knowledge bases all see meaningfully better recall once keyword indexes are replaced or supplemented with embeddings.
Recommendation engines. User and item behaviour gets embedded into the same vector space, so “customers who liked this” becomes a nearest-neighbour query rather than a hand-built rules engine. Real-time scoring against a live catalogue is what lets a retail app update recommendations the instant a shopper views a new product, rather than waiting for an overnight batch job.
Image and video similarity. Reverse-image lookup, duplicate-content detection and content moderation all rely on the same principle: encode the image as a vector, then search for visual neighbours. Digital asset management teams use this to find every variant of a logo or product photo scattered across a library of hundreds of thousands of files, a task keyword tagging alone cannot do reliably.
NLP tasks beyond search. Document clustering groups similar contracts or reports without manual labelling. Semantic question answering pulls the right passage from a document set even when the question is phrased nothing like the source text. Deduplication catches near-identical customer records or support tickets that differ only in punctuation or phrasing, something exact-match logic misses constantly.
A biotech-specific variant of the same idea is virtual screening, where molecular structures are embedded and searched for similarity to known compounds, a technique partners like Innova Biotech apply to accelerate early-stage drug discovery.
Modern AI-driven use cases: RAG, agents and multimodal search
Generative AI has given vector databases a second, arguably bigger job: keeping large language models grounded in fact.
Retrieval-augmented generation (RAG). An LLM on its own only knows what it was trained on, which means it invents answers when asked about anything more recent or more specific. RAG retrieves relevant passages from a vector database and injects them into the prompt before generation, which reduces hallucination and grounds answers in current, domain-specific content. This is the single most common reason enterprise teams adopt a vector database in 2026.
Agent memory. Conversational agents that forget everything after each session feel broken to users. Storing conversation history and user preferences as vectors gives an agent long-term memory it can query, producing a personalised experience rather than a stateless chatbot that repeats the same questions every visit. Vector search is now integral to enterprise agent platforms built for exactly this kind of persistent context.
Semantic caching. Repeated or near-identical LLM calls are expensive. A semantic cache checks whether a new prompt is similar enough to one already answered, and returns the cached response instead of calling the model again. This pattern can materially cut API spend for high-traffic applications where many users ask variations of the same question.
Multimodal search. Text, images and audio can now share a single embedding space, so a query can be a photo and the results can be product descriptions, or vice versa. That capability underpins visual search in retail and increasingly voice-driven interfaces in customer service.
Teams building this kind of stack often underestimate the architecture decisions that separate a working RAG pilot from a system that holds up under real traffic and real edge cases.
When should you use a dedicated vector database?
Not every project needs a standalone vector database, and choosing wrong in either direction wastes budget and engineering time.
Choose a dedicated system when you need sub-100ms P95 latency across tens of millions of vectors, high write throughput, or specialised index tuning that a general-purpose database cannot offer.
A Postgres or OpenSearch extension is often enough for smaller datasets, lower query volumes, or teams that want vector search alongside existing relational or lexical data without adding a new operational component.
Hybrid search scenarios, where results must satisfy both semantic relevance and exact filters (price range, permissions, date), push most teams towards platforms with native hybrid support rather than bolting filters onto pure vector search after the fact.
Weigh the operational cost. A dedicated vector database adds another system to monitor, scale and patch. If your current stack can absorb the workload without that overhead, it usually should.
Implementation considerations that decide whether a pilot survives contact with production
Index choice and compression settings are not one-time decisions. HNSW favours speed and recall; product quantisation trades some accuracy for a smaller memory footprint, a balance documented across index categories worth revisiting as data volume grows.
Pick an embedding model deliberately, and monitor for drift: as your data or user language shifts, older embeddings can drift out of sync with new ones, degrading relevance quietly.
Set a re-embedding cadence rather than treating vectors as permanent; quarterly reviews are common for fast-moving catalogues.
Scale through sharding, hardware acceleration (GPU-backed indexes), and caching layers rather than throwing more compute at a single node.
Chunk documents thoughtfully. A reference implementation for clinical semantic search uses 300-token chunks with 50-token overlap, a pattern that balances recall against latency in regulated, high-stakes domains.
Evaluate with real relevance metrics and A/B tests, not just vibes. Monitor query relevance over time, not only uptime.
Pro Tip: Log a sample of “near miss” queries, ones where the top result was close but not quite right, every week during your pilot. That log will tell you more about embedding quality than any dashboard.
How an end-to-end AI partner applies vector databases in practice
Sentient Concepts sees consultancy value concentrate at three points: choosing the right use case before writing a line of code, designing an architecture that survives real traffic, and governing the system once it is live.
Use-case selection: prioritising document processing and conversational agent projects where retrieval accuracy has a direct financial payoff, not just a technical one.
Architecture and integration: connecting embedding pipelines to existing document processing systems in finance and manufacturing without disrupting compliance workflows.
Managed operations: monitoring relevance and index health after launch, so degradation gets caught before it affects users rather than after a client complains.
That continuity, from strategy through build to run, is what separates a working industry deployment from a pilot that quietly stalls once the consultants leave.
Anomaly and fraud detection
Fraud teams have traditionally relied on threshold rules: flag any transaction over a fixed amount, or any login from a new country. Vector databases change this by representing behavioural patterns, spending habits, login sequences, device fingerprints, as vectors and searching for deviations from a customer’s normal pattern. This captures multi-dimensional anomalies that simple threshold rules miss, because fraud rarely announces itself through a single obvious signal.
A transaction that looks unremarkable on amount and location alone can still sit far from a customer’s typical behavioural vector once dozens of subtle signals are combined. That is the same mechanism behind predictive maintenance in manufacturing, where sensor readings are embedded and compared against normal operating patterns to catch equipment failure before it happens, and it is a pattern Sentient Concepts has applied directly in banking fraud detection work.
The trade-off is tuning. Behavioural vectors need enough historical data to establish a genuine baseline, and thresholds for “how far is too far” require careful calibration against false-positive costs, since flagging too aggressively burns analyst time on legitimate transactions.
What technology leaders consistently get wrong
The biggest strategic error is treating vector database selection as the hard problem, when data quality and evaluation almost always matter more. A well-chosen index on badly chunked, poorly labelled data still produces mediocre retrieval.
The second is neglecting monitoring. Relevance degrades quietly as language and content shift, and teams that ship a RAG system without ongoing evaluation find out it has drifted only when users complain.
Start with one high-value pilot, measure a real business metric, ticket resolution time, fraud catch rate, and expand from there rather than architecting for scale you do not yet have.
— Thomas Samuel
Ready to put vector search to work in your systems?
Sentient Concepts is the alternative to piecing together disconnected vendors for vector-driven AI: one team carries the project from strategy through build to ongoing operations, so there is no handoff gap where relevance quietly degrades after launch. That matters because the biggest failures in this space happen after go-live, not before it.
If your organisation is weighing RAG, semantic search, or fraud detection built on embeddings, the sensible next step is a readiness review rather than a leap straight into procurement. Sentient Concepts’ AI strategy and roadmap service assesses which use cases justify a dedicated vector database, and its managed AI operations team keeps the system tuned once it is live, so relevance regression gets caught internally rather than discovered by a customer. Start with a readiness conversation before committing budget to infrastructure you may not need.
Sources
FAQ
What are the main use cases of vector databases?
The core applications are semantic search, recommendation engines, image and video similarity search, retrieval-augmented generation for LLMs, agent memory, semantic caching, and anomaly or fraud detection.
What are five examples of vectors used in AI systems?
Common examples include text embeddings from documents, image embeddings from photos, user behaviour vectors for recommendations, audio embeddings for voice search, and molecular structure vectors used in drug discovery screening.
Are vector databases actually useful, or is this hype?
They are genuinely useful for any system that needs to match on meaning rather than exact text, particularly RAG, semantic search and fraud detection, though smaller workloads may not need a dedicated system at all.
What should I look for when choosing between vector database options?
Prioritise latency at your expected scale, write throughput, native hybrid search support, and index flexibility (HNSW versus quantised options), rather than choosing on feature-list length alone.
Does my organisation need a dedicated vector database or will an extension work?
If your dataset is small and query volume modest, a Postgres or OpenSearch vector extension is usually sufficient; move to a dedicated system once you need sub-100ms latency at tens of millions of vectors or heavy write throughput.
Recommended